For builders
When the model changes: the playbook
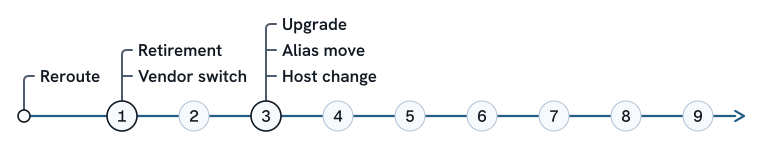
Nine steps, in order, for a retirement, an upgrade, an alias move, a reroute, a host change or a vendor switch, each with the page that helps you do it.
Any change in which model answers your requests is a model change, chosen or not. Our research on model-routing refusal tax showed a fallback firing on 20 of 28 calls and silently serving every rescued answer from a different, cheaper model. In our three-model reliability benchmark, one model’s median reply took 20.7 seconds, one call in ten ran past 431 seconds, and 8 of 347 planned calls never returned, so a new model can trade wrong answers for slow or missing ones. In the benchmark across two model generations, the provider blocked all 10 of one model’s deepest-chain calls, so that model’s score covers only 77.3% of the study’s reliability index. A model judge counts too: our catalog of judge biases and their tests notes that a judge’s measured biases can move when its model is swapped or updated under the same name.
When the model changes, in this order.
- List every model id in production, eval runs and judges, and look up each retirement date on the model lifecycle reference.
- Save the old model’s per-case results before the retirement date.
- Pin both sides to dated snapshots, then compare on the same cases, paired, with the prompt untouched. Use the eval A/B comparator.
- Re-validate the judge if it or its model changed.
- Track the switch item by item on the model upgrade checklist.
What changed sets the first step
- Retirement. The provider shuts down a dated snapshot and the model stops answering. Start at step 1 (inventory); the retirement date is the capture deadline.
- Upgrade. You choose a newer model from the same provider. Start at step 3 (pin both sides).
- Alias move. The model behind a name changes without a code change on your side. Start at step 3, and check whether recent eval runs and judge runs used the alias before or after the move.
- Reroute. A fallback or router sends some requests to a different model. Start by confirming which model answered: log refusals and model fallbacks.
- Host change. The same model is served from a different platform, such as a cloud partner, whose versions, defaults and retirement dates can differ. Start at step 3 and check all three on the new host.
- Vendor switch. You move to a model from a different provider. Start at step 1.
Capture the baseline early and run the canary late
Each step needs what the one before it produced.
- Inventory. List every model id in production, in eval runs and in judges, with its snapshot date or alias and its retirement date. Check the model lifecycle reference.
- Capture before the date. Save the old model’s per-case baseline before its retirement date. After the date the baseline cannot be regenerated. Import your existing results. If your evals ran on OpenAI’s hosted service, the OpenAI Evals migration guide covers the export order.
- Pin both sides. Fix both the old and new model to dated snapshots and fixed settings before comparing. An alias can move mid-comparison.1 The model lifecycle reference explains how an undated alias repoints.
- Check the judge and the harness before the model. Re-validate the judge when it or its model changes or retires. Judge the same outputs twice, as prove the suite can fail shows, and measure the judge’s error rates against people’s labels on the judge validation report. If the harness also changed, separate the harness offset with the harness migration score-continuity checker.
- Compare paired on the same frozen set, then look past the pass rate. Before the run, set the margin on the acceptance criteria builder: the largest drop you will accept. Run both versions on the same cases, same graders, same day, count refused or blocked calls as failures, and compare paired on the eval A/B comparator. Read the result against the margin on the no-regression verdict. Then read a fresh sample of the new model’s outputs on the error-analysis workbench, looking for failures your graders were not written to catch. Output format and tool-call contracts can break without an error, refusals on harmless requests can climb while the error dashboard stays flat, and latency under real load can change. Check the structured output failure rate and the latency budget calculator. Track every dimension on the model upgrade checklist.
- Re-tune the prompt on dev cases, score on held-out cases. Change the prompt only after the untouched comparison. A prompt format that works on one model can do poorly on another.2 A prompt tuned on the scored cases inflates the score on exactly those cases. Record that the two sets are separate on the model upgrade checklist.
- Recount and reprice on the new tokenizer. Claude 4.7 and later turn the same text into about 30% more tokens than earlier Claude models, by Anthropic’s count. Estimate the new count on the token counter and check the cost per successful task.
- Canary the change. Run the canary after the paired offline comparison. Size it on the canary release calculator.
- Record the change and tell customers. Record which model changed, when, what the comparison showed, and tell customers. The change-impact worksheet maps a model swap to the suites it touches. Track the dated record on the model upgrade checklist.
Footnotes
-
Chen et al., “How Is ChatGPT’s Behavior Changing over Time?”, arXiv preprint, 2023, https://arxiv.org/abs/2307.09009 (as of 2026-10-17): GPT-4’s prime-number identification accuracy moved from 84% to 51% between March and June 2023 on the same named service. ↩
-
Sclar et al., “Quantifying Language Models’ Sensitivity to Spurious Features in Prompt Design”, ICLR 2024, https://arxiv.org/abs/2310.11324 (as of 2026-10-17): prompt-format performance only weakly correlates between models. ↩